Skip to content
MCPBytes

Hand over a PDF.Your agent reads it, page by page.

Turn a PDF into clean text your agent can read, search and quote, even a 500-page one.

1 credit per 25 pages300 free credits to start

Available
  • API
  • MCP
MCP tool: extract_pdf

Before

paper.pdf12 pages

After

48,211 characters
  • text.txt
  • pages.json
C1Extract text from a PDFExample output. Every page starts with a --- Page N --- marker.

Long documents, made readable.

Send a PDF and get back its text, with every page clearly marked. Your agent reads the start right away and the rest in bite-sized pieces, so even a long report never overwhelms it, and it can jump straight to any page. Scanned pages without a text layer come back empty.

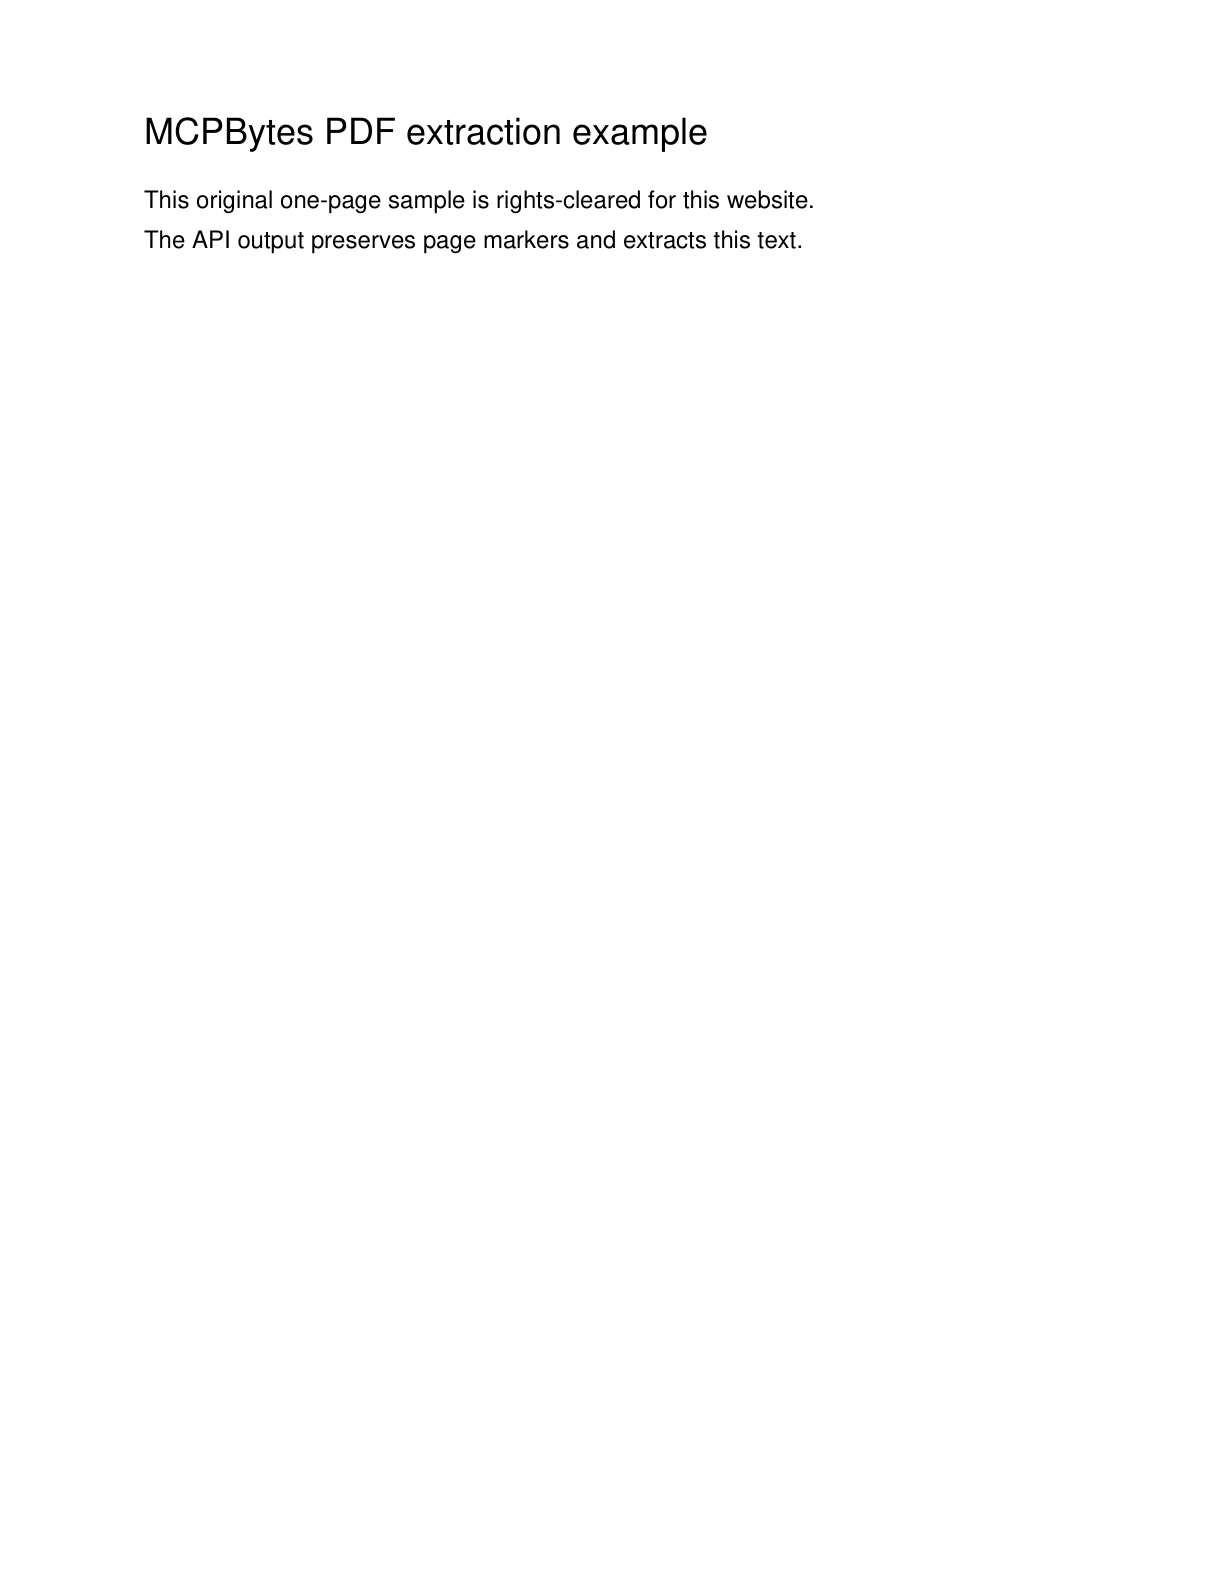
Compare the original one-page PDF with text.txt from one retained API job; scanned pages still need OCR elsewhere.

Source PDF

One original, rights-cleared page sent to extract_pdf.

Rendered first page of the original PDF: MCPBytes PDF extraction example, followed by two sentences about the sample and its text output.

A rendering of the original page. Download the source PDF.

Actual text.txt

Job j_452n79j33vc2gd785sd70vrkvx · 1 page · 160 characters

--- Page 1 ---
MCPBytes PDF extraction example

This original one-page sample is rights-cleared for this website.
The API output preserves page markers and extracts this text.

This tool extracts a PDF's text layer; it does not perform OCR. Tables and multi-column pages may need care when quoted.

The source and output above are the retained files from one approved API job, not a template response or a benchmark.
Input format
.pdf (not password-protected)
Pages
Up to your account's page limit per job; continue with start_page
Outputs
text.txt with page markers, pages.json with page offsets and metadata
Reading
First bytes inline over MCP; the rest in chunks of up to 100,000 bytes
Scanned pages
No OCR: pages without a text layer come back empty

Page by page.

Every page is marked, so your agent can cite it or jump straight to it.

Small bites.

Your agent reads as much as it needs, a piece at a time, instead of the whole file at once.

Just the part you need.

Pick a range of pages. Fewer pages cost less.

Download the example.

Inspect the files before running your own job. No sign-in required.

  • Source PDF

    Original one-page, rights-cleared sample sent to extract_pdf.

    PDF · 1 KB

  • Extracted text

    Actual text.txt output from job j_452n79j33vc2gd785sd70vrkvx, including its page marker.

    TXT · 1 KB

  • Page offsets

    Actual pages.json output from the same one-page job.

    JSON · 1 KB

Pay by the job.

Costs 1 credit per 25 pages (at least 1). A job that fails costs nothing.

Pricing details

Start free

Available now

300free credits when you sign up

  • Every MCPBytes tool, one credit balance
  • Sign in with GitHub or email, no card required
  • Each tool states its price before you run it
  • Failed API jobs cost nothing

Price per job

Extract text from a PDF

Per 25 pages
1 credit

Limits by account

Most pages
Free500
Pay as you go5,000
Monthly bundle5,000
Largest input
Free20 MB
Pay as you go100 MB
Monthly bundle100 MB
Jobs at once
Free3 jobs
Pay as you go5 jobs
Monthly bundle8 jobs
Results kept
Free1 day
Pay as you go7 days
Monthly bundle30 days
Largest upload
Free50 MB
Pay as you go100 MB
Monthly bundle100 MB
Longest run
Free10 min
Pay as you go14 min 30 s
Monthly bundle14 min 30 s

Free until your first purchase; any credit pack moves you to Pay as you go; a monthly bundle while it lasts. Compare accounts

Your agent or your code.

Connect your agent and it can use this tool right away, or call it from your own code. One key works for both.

Start a job

Send a file body, or JSON containing an upload ID or public URL. Options such as start_page go in the JSON options object, or the query string for a file body.

# The PDF is the request body
curl "https://api.mcpbytes.com/v1/tools/extract_pdf/jobs?filename=paper.pdf" \
  -H "Authorization: Bearer $MCPBYTES_API_KEY" \
  --data-binary @paper.pdf
Response202 Accepted
{
  "id": "j_7c2m9x4f1q8w3e6r5t0y2u7i9o",
  "tool": "extract_pdf",
  "status": "queued",
  "input": {
    "name": "paper.pdf",
    "bytes": 1204331,
    "source": "body"
  },
  "options": {
    "start_page": 1,
    "max_pages": 500
  },
  "error": null,
  "result": null,
  "compute_ms": null,
  "credits_charged": null,
  "created_at": "2026-09-19T12:00:00.000Z",
  "started_at": null,
  "finished_at": null,
  "outputs_expire_at": "2026-09-20T12:00:00.000Z"
}

Get the result

Poll until the status is final. Download files only after success.

Requestread.sh
# JOB_ID is the id from the create response
curl https://api.mcpbytes.com/v1/jobs/$JOB_ID \
  -H "Authorization: Bearer $MCPBYTES_API_KEY"

# Read the text, 20,000 bytes at a time
curl "https://api.mcpbytes.com/v1/jobs/$JOB_ID/files/text.txt?offset=0" \
  -H "Authorization: Bearer $MCPBYTES_API_KEY"
Response200 OK · trimmed
{
  "id": "j_7c2m9x4f1q8w3e6r5t0y2u7i9o",
  "tool": "extract_pdf",
  "status": "succeeded",
  "result": {
    "files": [
      {
        "name": "pages.json",
        "bytes": 1842,
        "sha256": "…",
        "url": "https://api.mcpbytes.com/blob/dl/j_7c2m9x4f1q8w3e6r5t0y2u7i9o/pages.json?t=…"
      },
      {
        "name": "text.txt",
        "bytes": 48903,
        "sha256": "…",
        "url": "https://api.mcpbytes.com/blob/dl/j_7c2m9x4f1q8w3e6r5t0y2u7i9o/text.txt?t=…"
      }
    ],
    "pages": 12,
    "first_page": 1,
    "last_page": 12,
    "empty_pages": 0,
    "chars": 48211,
    "notes": []
  },
  "compute_ms": 1310,
  "credits_charged": 1,
  "finished_at": "2026-09-19T12:00:03.000Z",
  "outputs_expire_at": "2026-09-20T12:00:00.000Z"
}
MCP

Connect once. Your agent calls extract_pdf and gets the download URLs back. This endpoint has only this tool's family, which keeps your agent's tool list short; one endpoint has every tool.

Claude Code

The first form signs in through the browser when you run /mcp. In .mcp.json (project root), ${MCPBYTES_API_KEY} is read from the environment when Claude Code connects. Claude Code docs

claude mcp add --transport http mcpbytes \
  https://api.mcpbytes.com/mcp/pdf
Codex (CLI, IDE extension, ChatGPT desktop)

Codex reads the key from the environment variable each time it connects. The same table can go in ~/.codex/config.toml by hand; codex mcp add has no --header flag. Codex docs

codex mcp add mcpbytes --url https://api.mcpbytes.com/mcp/pdf \
  --bearer-token-env-var MCPBYTES_API_KEY
Cursor

~/.cursor/mcp.json (all projects) or .cursor/mcp.json (one project). Remote servers take no "type". Without the header, the client signs you in with GitHub or an email link (OAuth). Cursor docs

~/.cursor/mcp.json
{
  "mcpServers": {
    "mcpbytes": {
      "url": "https://api.mcpbytes.com/mcp/pdf",
      "headers": {
        "Authorization": "Bearer ${env:MCPBYTES_API_KEY}"
      }
    }
  }
}
11 more clients in the docs →
MCP tools
extract_pdf
Starts a job that extracts the text of a PDF, page by page, and returns the beginning of it; continue with read_job_file (text.txt). pages.json has per-page offsets and the document metadata. Scanned pages have no text (no OCR). Give upload_id (from create_upload) or a public https url. Waits up to wait_seconds for the result. Costs 1 credit per 25 pages (at least 1).
create_upload
Returns a one-hour URL to PUT a local file to; then call the tool with the upload_id.
get_job
Status and results of a job; waits up to wait_seconds for it to finish.
cancel_job
Cancel a queued job or a workflow whose can_cancel is true; repeated calls never delete results.
list_jobs
Your most recent jobs, newest first.
read_job_file
Reads a text output (.txt .json .md .csv) of a succeeded job in chunks.
Full reference: inputs, options, outputs, limits and errors

Your first jobs are on us.

Start with 300 free credits. Sign in with GitHub or email and try a tool in your browser. No card required.